Categories
Personal Publishing Social Software

How do we find information in the Blogosphere?

It has become almost a truism in critical examinations of the Blogosphere to talk about how – with the explosion in weblog numbers – it becomes difficult to find the best insights on any given subject. I first came into contact with the clear expression of this idea in an article called Scaling Clay Shirky but it’s recently been pretty much everywhere…

I believe that there are some legitimate concerns in these sentiments, but I think fundamentally they miss the point – it’s my opinion that replication of content online and a massive increase in the number people posting about a specific issue does not constitute a problem for the blogosphere, but instead one of its most significant advantages. In fact I’d go further and say that where there are problems, these can be resolved by simply speeding up the self-organising mechanisms that are implicit within the blogosphere, which is, I think what sites like Daypop, Blogdex, Popdex and Technorati are currently doing, albeit in a reasonably primitive way. But I’m getting ahead of myself. Today I’m just going to talk about How do we reach 100% information saturation on any given subject in the blogosphere without reading anywhere near 100% of the weblogs in it? Or to put it another way: With everyone posting lots, does the system help me find the good stuff?

  • Before I start though – here’s a simplified, and easier to assimilate / read pdf version of what I’m about to say: scaling_clay_shirky.pdf [75k]

Let’s start off by aggregating all the possible insights about a given subject from all the weblogs that specifically refer to it. This total aggregation will represent 100% of the information available on the subject in the blogosphere at a point in time.

If information was distributed evenly throughout webloggery and weblogs were read randomly then take-up of information would be linear and stable – in order to get 100% of the insights, you’d have to read 100% of the weblogs.
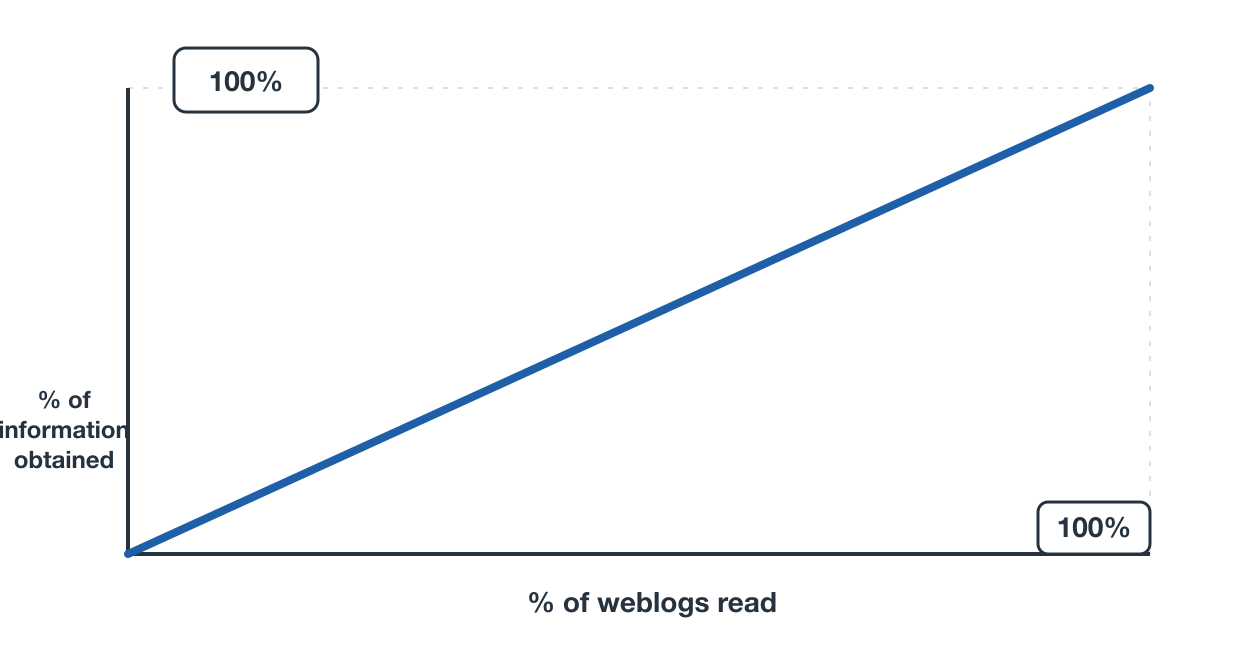
Linear gradient

[In this first graph I’ve plotted on the left the amount of information that you’ve managed to assimilate versus (on the right) the percentage of the weblogs that you’d have to read in order to get that amount of information – in the very specific special case that information is distributed evenly and randomly. The features of this “special case” will gradually be removed over the rest of the article. Another point I should perhaps clarify is that I’ve tried to conceive of the bottom axis as also including the order in which one reads the weblogs – that should become clearer through the article…]

However, we know it to be the case that information will not be distributed evenly throughout these weblogs. Many weblogs will contain limited information of any kind. Some will contain a lot. Many will contain replicated information that could easily be found on other sites.
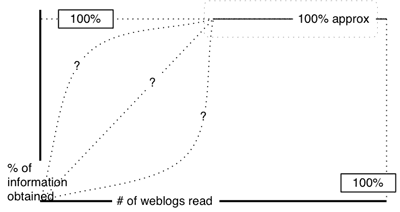
Graph reaches 100% earlier

In this graph, ignore for the moment the dotted lines on the left. they represent nothing but the uncertainly fo the beginning of the curve. This diagram takes into account that weblogs have different levels of insight withint them, and that information is often replicated (either by active memetic spread or because the insights are simple and common). In the vast majority of cases then – even given that you’re still reading weblogs in a totally arbitrary order – it’s likely that you’ll get extremely close to the 100% saturation point a significant way before you’ve read 100% of the available weblogs.

In practice – again assuming that you were reading the weblogs in a random order, it would be impossible to gauge the particulars of the curve that led up to the near-as-dammit-to-100% information saturation point. A sample curve would probably be organised in a series of steps – with gradual accretion of insight being the normal, but with occasional significant massive leaps also occurring.
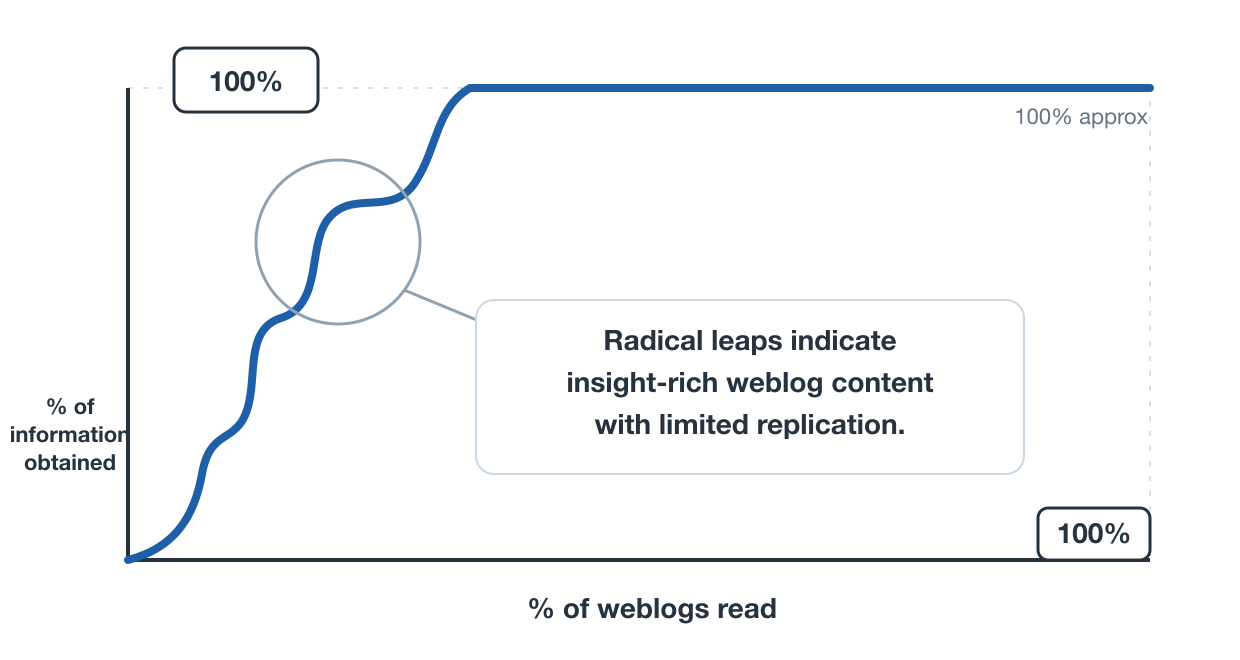
The line becomes a series of progressive steps

Now – all these models have been based upon the assumption that the order in which the weblogs are read will be random. In fact nothing could be further from the truth. Some weblogs are clearly more likely to be read – this is not necessarily purely based upon the value of their contributions, but it’s not completely distinct from such valuations either. It would probably be fair to say that on average well-linked-to sites are more likely (albeit perhaps only incrementally) to contain insight than sites which are not linked to at all. Secondly, if someone does produce content of value and insight on any specific subject, then it is more likely to be linked to – which in turn increases the likelihood that an individual will visit the site in question.

Both of these criteria suggest that (in our attempts to reach the 100% insight threshold) we will be more likely to be initially directed to high-insight sites than low-insight sites. This changes our graph substantially.
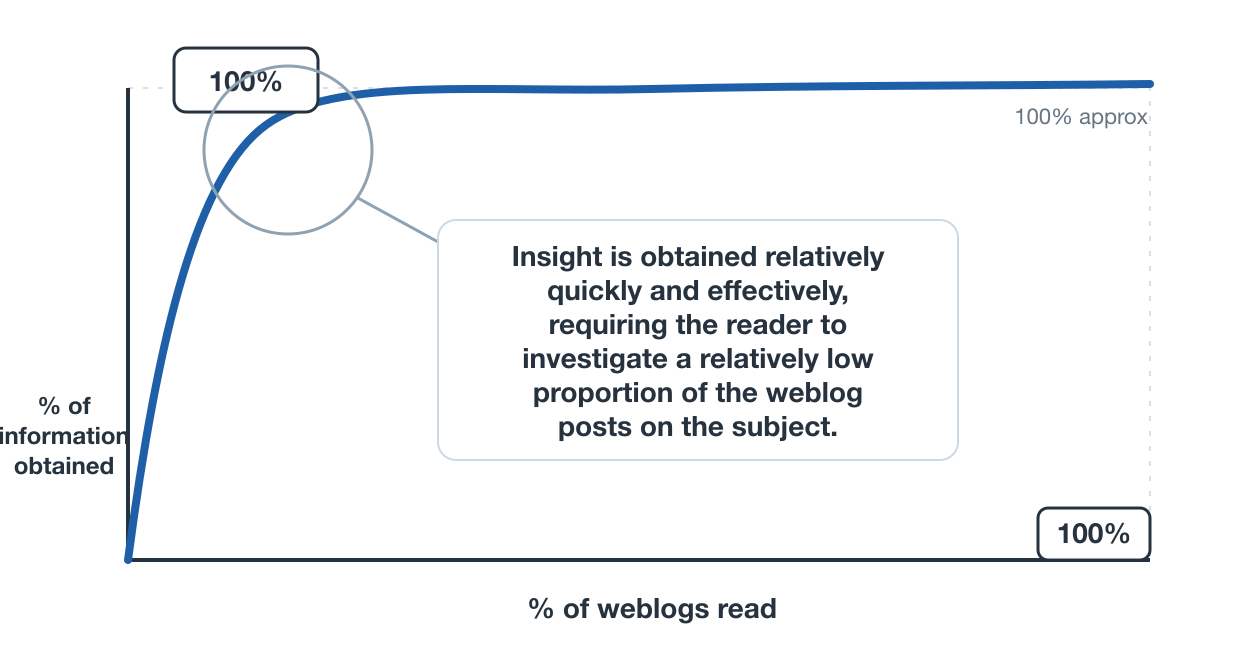
The graph starts strong and levels off close to 100%

It seems likely, in other words, that even if there’s a limited tendency for sites with more insight to be read first – then the information accretion would be remarkably steep initially and the level off dramatically close to the 100% saturation point.

Hypothetical conclusions: For any given body of information on weblogs, no matter the rate of replication of information or the number of people who post exactly the same comments, close to 100% of the available insight can be reviewed by reading a disproportionately small number of sites – sites that will – as a rule – be among the first that they stumble across through their normal browsing and research patterns.

Related Hypotheses perhaps worth exploring: (1) The larger the number of posts about a subject (and hence the more likely replication) the smaller the proportion of those sites that need to be read in order to have reviewed close to 100% of the available insight. (2) The size of the available insight will increase as the number of posts about a subject increases (although perhaps not in linear proportion).

The images were replaced on 5 August 2026 for clarity. The originals are available here, here and here.
Categories
Random

Remodelling…

While I have the opportunity, I’m trying to get a few things done around the site. I’ve removed the files section of the site (which is where I used to put all my longer pieces) and I’ve put those posts back into the rest of the site. And to make it easier to find them (and some other stuff from around the weblog that’s worth preserving), I’ve created a best of… section that is essentially a categorised guide to stuff that other people might actually find useful.

I still think there’s some woolliness around the edges, and please god don’t read the introductory copy on some of the category pages – it’s bloody terrible. But at least this now does mean (for example) that I can start pointing towards the social software or the personal publishing parts of the site… And no – I’ve not planned for separate RSS feeds yet, so don’t even ask…

Categories
Random

What's happening at UMS…

I’ve just been reading the Media Guardian’s piece on uSwitch buying UpMyStreet. Obviously closest to my heart is what they’re going to be doing with Conversations, which I think many of us believed was only the beginning of what we could do around geocoded community features. I’m delighted to hear that they’re still going to running it – even developing it further – although obviously it’s disappointing not to be part of that process…

The site, which has 650,000 unique users a month, recently launched a message board service called Conversations that allows neighbours to contact one another. Mr Salmon said that this area would also be developed in order to get people to return more often. “I want it to be a site that people go to every day in the same way they would the BBC or a financial news site,” he said.

Categories
Life

###Tom For Sale###

As many of you know, UpMyStreet.com – the company where I have worked for the last ten months – put itself up for sale a few weeks ago. Many of my co-workers prudently put their CVs online at that time, but for a variety of reasons, until now I’ve not done so. Yesterday a deal was finally struck which sold UpMyStreet to uSwitch, but unfortunately the other company’s offer was not for the entire organisation (cf. Stefan’s comments).

As a result – effective immediately – I now find myself looking for a new project to work on. Ideally, I’d be looking to be developing some new social software or community projects (either public-facing or within organisations) or to work around personal publishing and user-generated content. However, I’m also open to possibilities in other areas, so if there’s something you’d like to discuss with me, let me know…

If you have any questions, suggestions or are looking for clarification on anything, then please don’t hesitate to contact me directly – My e-mail address is on my CV.

Categories
Random

The pure unadulterated Joy of Linkage…

For a variety of reasons that I’ll go into later in the day, I’ve not found myself able to post for a good few days now, so I think I’m going to get myself back into the swing of things by a quick block of back-to-basics weblogging. All that follows is simple, entertaining and fun. Nothing intellectually stimulating, nothing ideologically threatening, nothing (indeed) about social software. Just good quality linkage:

Categories
Random

UkBloggers discuss…

For anyone out there who is interested in another avenue for the discussion of weblog culture – particularly in the UK – I can particularly recommend the UK Bloggers Discuss list at the moment…

Categories
Social Software

My working definition of social software…

A while ago I wrote about a potential definition of social software based around Englebart’s theories of augmentation. Shortly before I went to ETCon I was talking about related issues with Will Davies of the iSociety and included (in my comments) a revised version of that definition, which I have since revised still further. So then, this is my current rough working definition of what it is I’m talking about when I’m talking about social software.

Social software is a particular sub-class of software-prosthesis that concerns itself with the augmentation of human social and / or collaborative abilities through structured mediation (this mediation may be distributed or centalised, top-down or bottom-up/emergent). Social software augments these abilities by:

  1. Removing the real-world limitations placed on social and / or collaborative behaviour by factors such as language, geography, background, financial status, etc;
    [This can also be seen as the basic aspiration of first-generation online discussion software as well as the gist of the world-changing hyperbolae of the press during the dot com years]
  2. Compensating for human inadequacies in processing, maintaining or developing social and / or collaborative mechanisms – in terms of information overload, generating appropriate filtering mechanisms, building in solutions to compensate for reptile-brain activity, developing structures that are immune to blame-culture, recrimination etc. This in particular can be seen as the replacement of the inherent limitations of geography (1 above) with mechanisms that generate parallel senses of ‘similar, different’, ‘near, far’ etc. This also includes feedback loops and the like;
    [Some of the more interesting work that people have been talking about already sits in this area – particularly Clay’s work on groups when he’s quoting Bion.]
  3. Creating environments or distributed tool-sets that pull useful end results out of human social and / or collaborative behaviour – for example, generating software that facilitates human creative processes in groups, structuring the process (or having the process emerge through apparently unrelated interactions) so as to have a distinct and productive end result;

That’s probably as close as I’ve got as of yet… Any thoughts?

Categories
Politics Science Social Software

Steven Pinker and the Perfectibility of Man…

There’s fragments of a paper in my head. I need to find ways of noting this stuff down that doesn’t collide with my writing on this site. It goes back before Clay, to a place of darkness that is somewhere around the edges of some work I did in classics about a million years ago around constructivist and essentialist views of human nature and history (of which there is much written). Arts disciplines normally concentrate on that which makes the past a different place – alien and weird. Science concentrates on what is permanent and unyielding. The questions are always relational – is science skeletal to humanities meat (or meat to skin maybe)? Are the bones of science demonstrated to be brittle by philosophical poststructuralist critiques? Or are the relativisms of cultural studies shed like the masquerading shell of a scientific Terminator?

So this is the point where I talk about Freud and my interest in models of the mind at that abstracted level – that it’s maybe ‘unscientific’, but it’s still essentialising (just at a different level). I delivered a paper on anachronism and identification in Aristotle and Freud a million years ago at a conference in New York. I can’t remember what I said – and I finished it on sheets of hotel stationary while inhaling the minibar, so I’ll probably never find a useful copy of it anywhere either… Maybe there’s stuff that’s permanent – maybe we just accept that. I believed that then and I think I believe it now… Interesting, but not obvious questions these – whatever you may wish to believe…

So Steven Pinker’s on TV and he’s talking about the perfectibility of man and that sense of a “Blank Slate” that he writes about in his latest book of the same name. And he’s talking about stuff I already knew, but I don’t know where from – the association of the political left with ideologies that deny human nature as something fixed and permanent (which explains to me the resistance that feminism always had to Freud and reminds me of an incredibly brief and nerve-wracking conversation that I had with Alan Sinfield [profile] back when I was an intellectual before I became an artisan). He said that Freud was “bad for gay people”. Same thing. Is essentialising philosophy bad for the left? Anyway – and Pinker is also talking about the right’s acceptance of natural humanity – that the right operates on assumptions that society works around and in concert with fundamental humanity (greed, acquisition, ambition, competition) while the left abstracts out – tries to find ways to make the world more fair by denying or suggesting we change human nature… [cf Juliet Mitchell’s earlier work]. That this ideology of human perfectibility can be considered to lie behind China’s revolution and communist ideology (for example) which considered people malleable enough to be transformed into good non-competitive, collaborative citizens.

And anyway – so I’m back to thinking about Clay again and how much my personal ideologies of community development and the value of social software coincide with his, but that at the same time the statements that he made at ETCon (that I missed, but which were extensions of comments that I’ve heard him say before) are not obvious – “groups act against their own interests” is a statement that needs contextualising. And that although we may feel comfortable asserting it, the ways in which studies of this kind are phrased and the fact that they are based on statements of limited cultural or historical difference between individuals – of an essentialised abstracted almost timeless humanity – might be correct, but are also implicated in much larger battles about the nature of identity and what it means to be human, and what is permanent and what can change. That difference between human groups is obvious and pronounced in many areas of hierarchy and interaction – as obvious as the similarities and that the line between what is human nature and what is acculturation or interpolation/relationships with language is not and may never be entirely clear. Which is not to say that it’s not appropriate to use research of this kind as the basis for social software work – simply that the very principle that we balance out inbuilt human limitations with prostheses and band aids (this is very much core to one of the senses of social software that I’m most comfortable with) is potentially wrapped up in a much larger and scarier and less morally or politically obvious debate than we tend to acknowledge…

This may make no sense to people who aren’t me. It’s messy enough to be only vaguely useful for me – gestural vocabularies, messy arguments and references are all I can offer… But maybe it’ll help me feel less uncomfortable with some of the collisions between my current and previous occupations…

Categories
Random

The Webb 2000…

While we were in San Francisco, my Webb 2000 started to act up a bit. So I did what anyone else would have done, I went to the depot to see if I could get him fixed. Turns out there was very little wrong with him – he just needed a quick mental service. That’s the problem with these high-powered models. You get tremendous speed out of them – great power – but the parts wear out so quickly. While I was there I checked out some of the other models available, but although there was no obvious difference between any of them, I found I’d grown rather attached to mine. So I just got him some coolant, and we went back to work…

many_robot_matts.jpg

Categories
Random

Maxicontent votes…

My browsers (both Camino and Safari) are now totally drunk on information. They’re so full of tabs and bookmark-bar stored links that they’re sluggish and clumsy and unresponsive. So in an attempt to help them back to a semblence of normality, I’m going to stick two metaphorical fingers down their collective throats and help them vomit up their linky goodness all over the blogosphere in the form of a massive blast of microcontent votage:

  • Ben’s Brain on Blog
    One of the best experiences of ETCon for me was actually getting to know Mr Hammersley a bit. I had tremendously good fun arsing around with him in arch-English accents in the middle of the Westin hotel while Webb looked on indulgently. While we were out there he told us about these places you could go and pay $1000 for a full body scan. And now he’s gone and done it for the Guardian. I’m looking forward to reading about that…

  • Awesome USBV spywatch
    It’s probably the least comfortable piece of tech ever made (apart from some chastity belts that Webb kept talking about in San Francisco – but you can’t put MP3s on them). Probably best to wait until tech like this is bluetooth-enabled. That would actually be pretty useful;

  • Meatball on Feature Karma
    I like the concept of “Feature Karma”, which basically says that every time you add a feature you should simplify another one or even remove it. That way you keep a site or a software project clean and simple and user-intuitive. It’s more use as a buzz-word or a piece of short-hand, though – since you’d have to find the optimum level of simplicity / utility first, otherwise you’d never have any functionality at all…

  • Defining Spam
    Wired’s coverage of the efforts to legislate against spam e-mail has been uniformly intelligent, apposite and good-natured. The most frustrating part of the debate is the obvious self-serving of some of the people concerned. Here’s a bit of the article: Wientzen argued that marketers should be able to contact consumers “at least once” by e-mail to ascertain whether the individual might be interested in receiving marketing messages. “How do you send solicited e-mails if there is no way to initially solicit interest?” he asked. The crowd responded with boos. How profoundly stupid can you be? You can’t encourage people to respond to those e-mails to help out the legitimate marketers if – in the process – it would get horribly abused by a thousand times as many illegitimate ones!